


Datasembly
Real-Time Pricing Data Platform
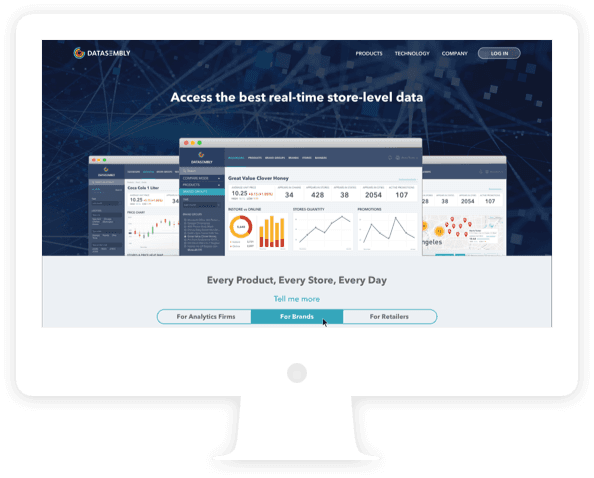
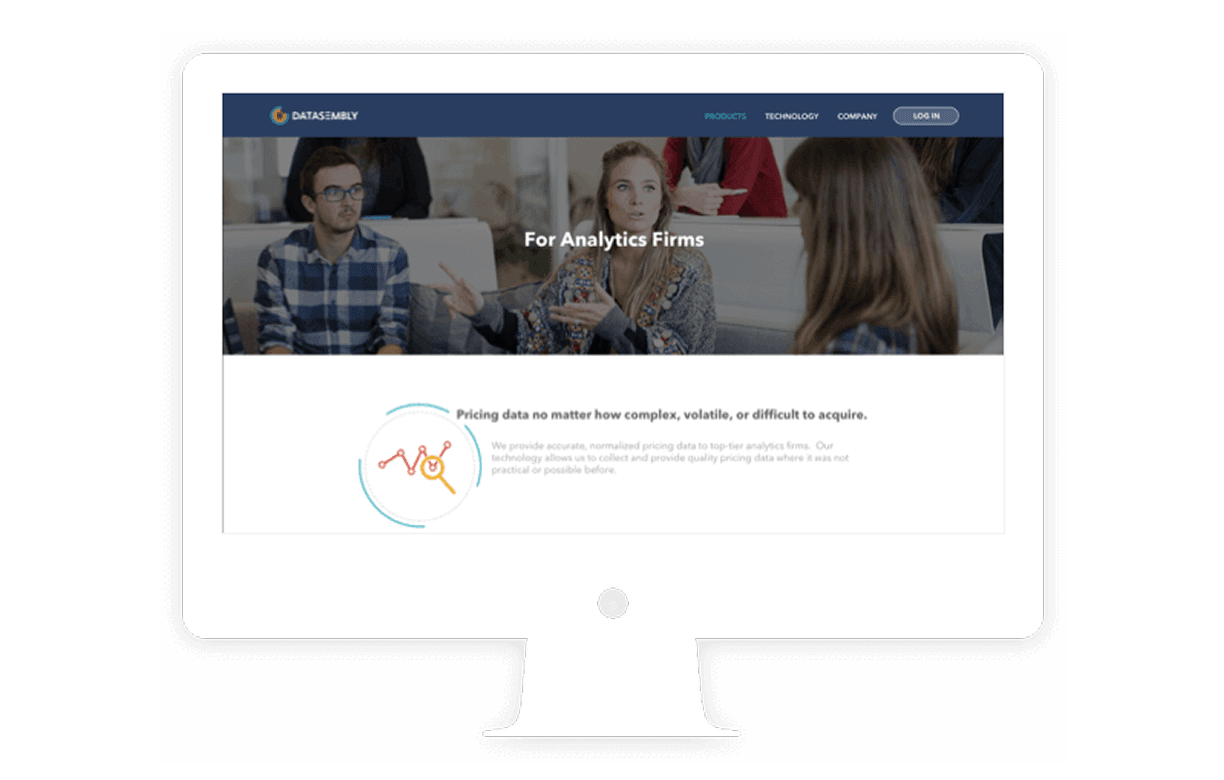
Datasembly provides access to millions of grocery and retail pricing records aggregated from hundreds of grocery delivery and online shopping websites. This data is hyper-local, highly volatile, and notoriously difficult to collect. Using specialised technology, Datasembly aggregates and transforms it so organisations can use it effectively.

Platform:
Web

Industry:
Trade

Team size:
3 people

Country:
USA

Project Duration:
2 years

The year started & completed:
2016
We built the platform that scrapes, aggregates, and transforms grocery and retail pricing from hundreds of websites into data organisations can query by store and by zip code.
Scope and Objectives
01
Aggregation from Hundreds of Sources
02
Store and Zip Code Granularity
03
Prices, Availability, and Promotions
04
Transformation for Analysis
Focus Areas and Deliverables
Scraping and Parsing
Play libraries handle the HTTP requests out to the source sites, with Play JSON and JSoup parsing the JSON and HTML that comes back from hundreds of differently built websites.
Real-Time Aggregation During Scraping
Postgres carries the real-time aggregations performed while scraping is still in progress, so figures are ready as the data lands.
Pipeline into the Warehouse
AWS Kinesis moves the collected data into AWS Redshift, which holds the stored pricing records.
Distributed Processing
Spark populates the Cassandra database, handling the volume that comes with millions of records refreshed against volatile prices.
Challenges Identified
Hyper-Local Prices
Grocery pricing varies store by store and zip code by zip code, so the platform had to collect and hold data at that granularity for it to mean anything.
Highly Volatile Data
Prices and promotions move constantly, so collection had to keep pace with them: stale data makes an analysis worse than useless to the organisation relying on it.
Notoriously Difficult Collection
Hundreds of grocery delivery and online shopping sites each present their data differently, which is why the collection side needed specialised technology built for the job.
Volume at Every Stage
Millions of records had to move from scraping through aggregation and into the warehouse quickly enough to stay current, which shaped the choice of a streaming pipeline and distributed processing.
Results of the Project
Unprecedented access to grocery and retail prices collected from the web.
Prices are collected for each store and zip code, allowing customers to track who is selling what, where, and for how much.
Datasembly's up-to-date data empowers organisations to make fast, informed, data-driven decisions, with prices, availability, and promotion data covering all their geographies, all their products, and all their competition.
Business Value
Pricing intelligence at the granularity retail decisions are actually made at.
Visibility Down to the Zip Code
Store-level and zip-code-level pricing shows who is selling what, where, and for how much, which is the detail a national average hides.
Data Fresh Enough to Act On
Continuous collection against volatile prices keeps the data current, so decisions rest on what the market looks like now.
Complete Competitive Coverage
Prices, availability, and promotions across every geography, product, and competitor give a full picture in one place.
Collection Handled as a Service
Customers get the aggregated, transformed result while the difficult work of gathering it from hundreds of sites sits with the platform.
Tools & Technologies
Akka
Redshift